ImprovementModels ·
DeepSeek V4.1 Flash
What it does
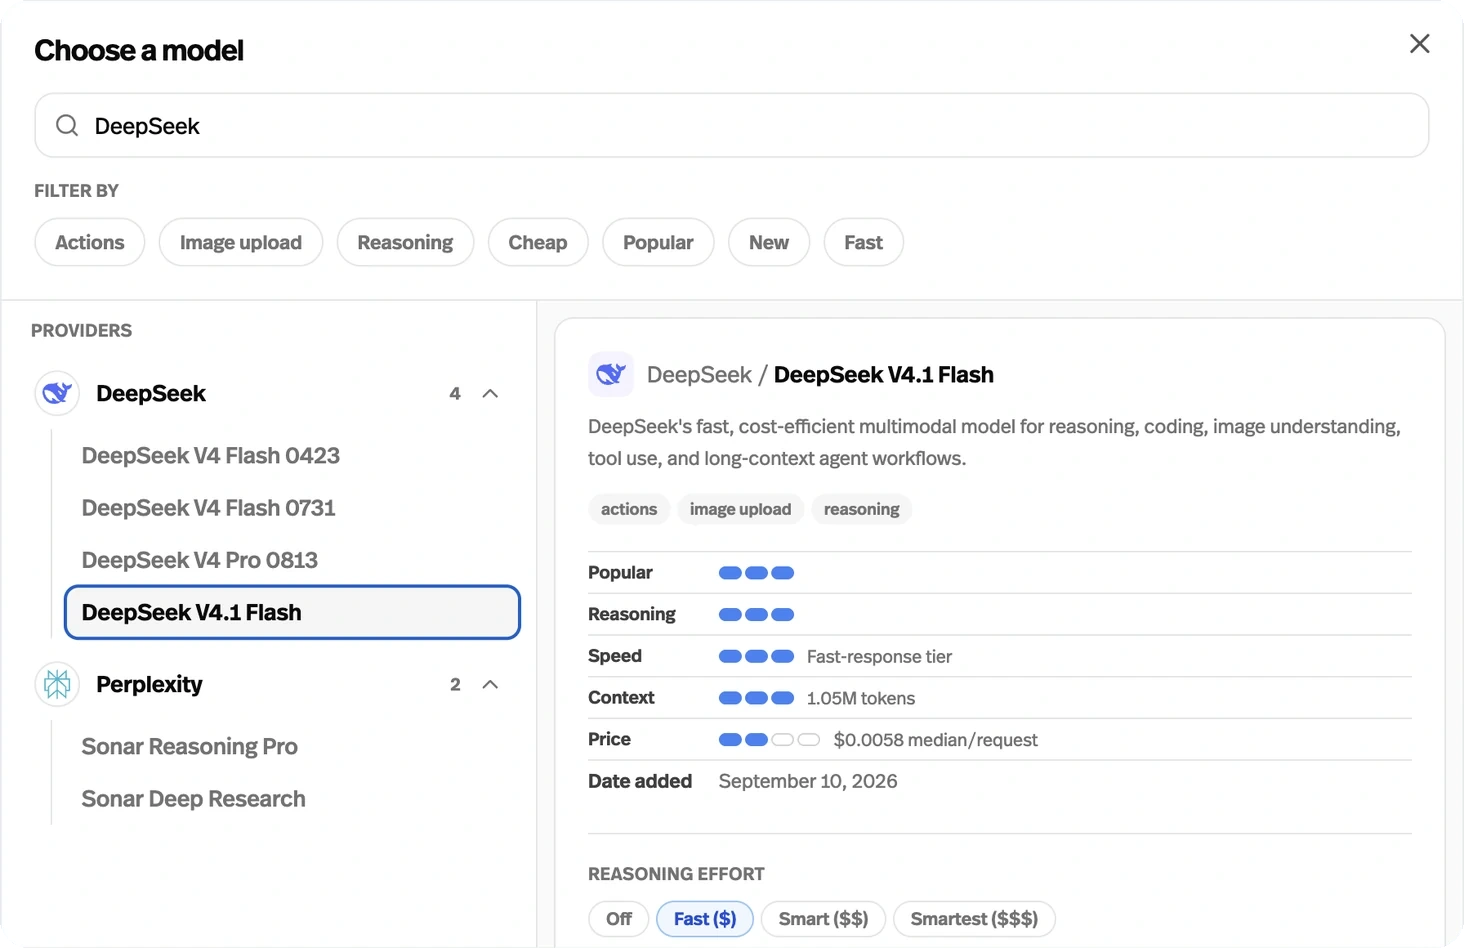
DeepSeek V4.1 Flash adds another model choice with image input, adjustable reasoning, and Actions.
Before this
An expansion. The earlier DeepSeek V4 Flash choices accepted text; V4.1 Flash adds native image input.
Why it matters
Use screenshots or charts alongside text in a DeepSeek-powered agent.
The specs
The model supports a 1,048,576-token context window, an output ceiling of 384,000 tokens, text and image input, and Actions; your agent’s configured limits still apply.
In the model picker, reasoning can be Off, Fast ($), Smart ($$), or Smartest ($$$).